Claude Now Leads 26% of Anthropic’s AI Research Inside the R&D Automation Index



A new internal measurement shows how much of AI research is now done by AI itself, and how Anthropic decided where to draw the line on autonomy.
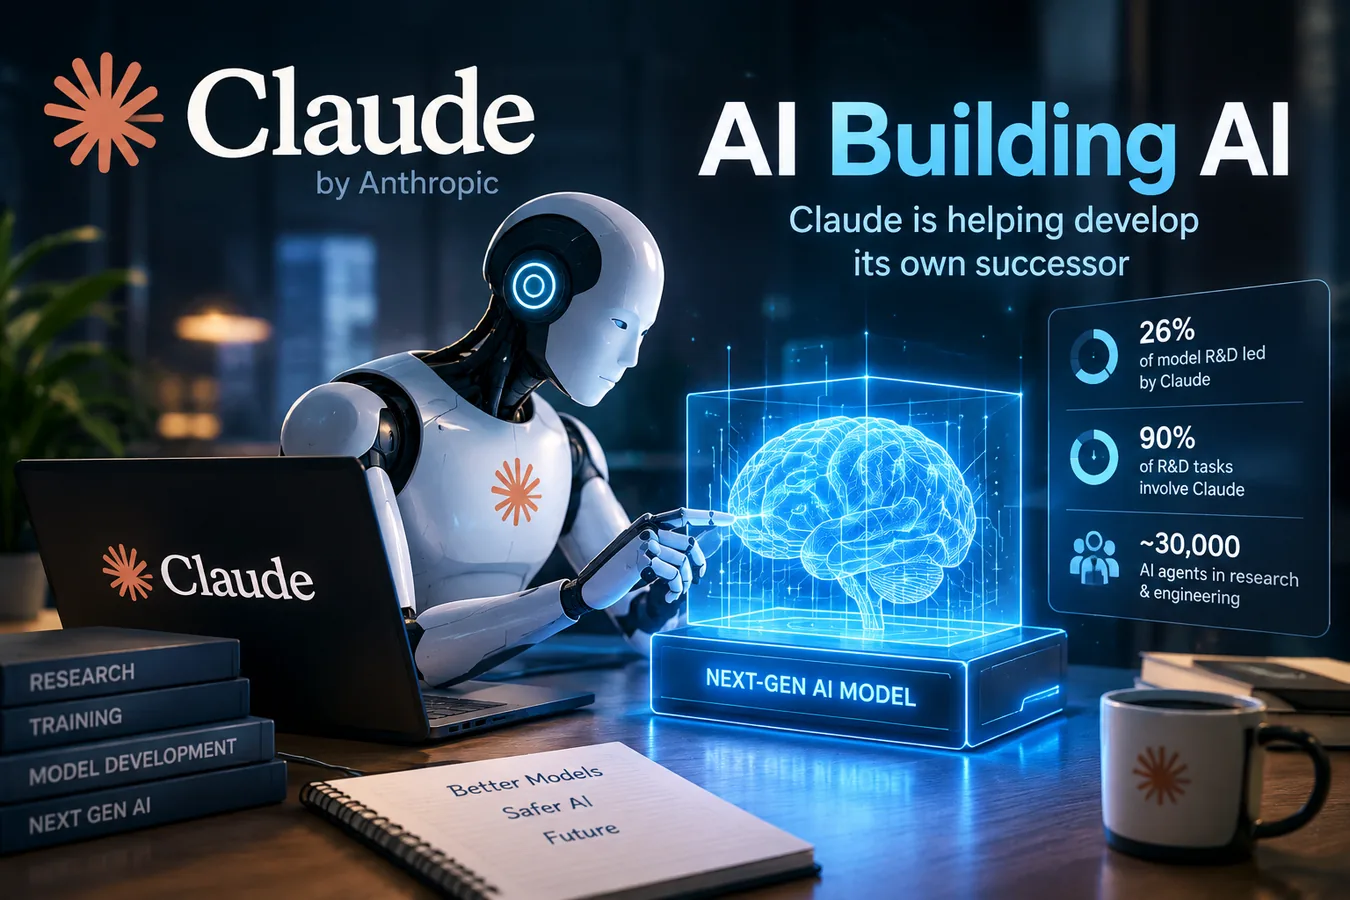
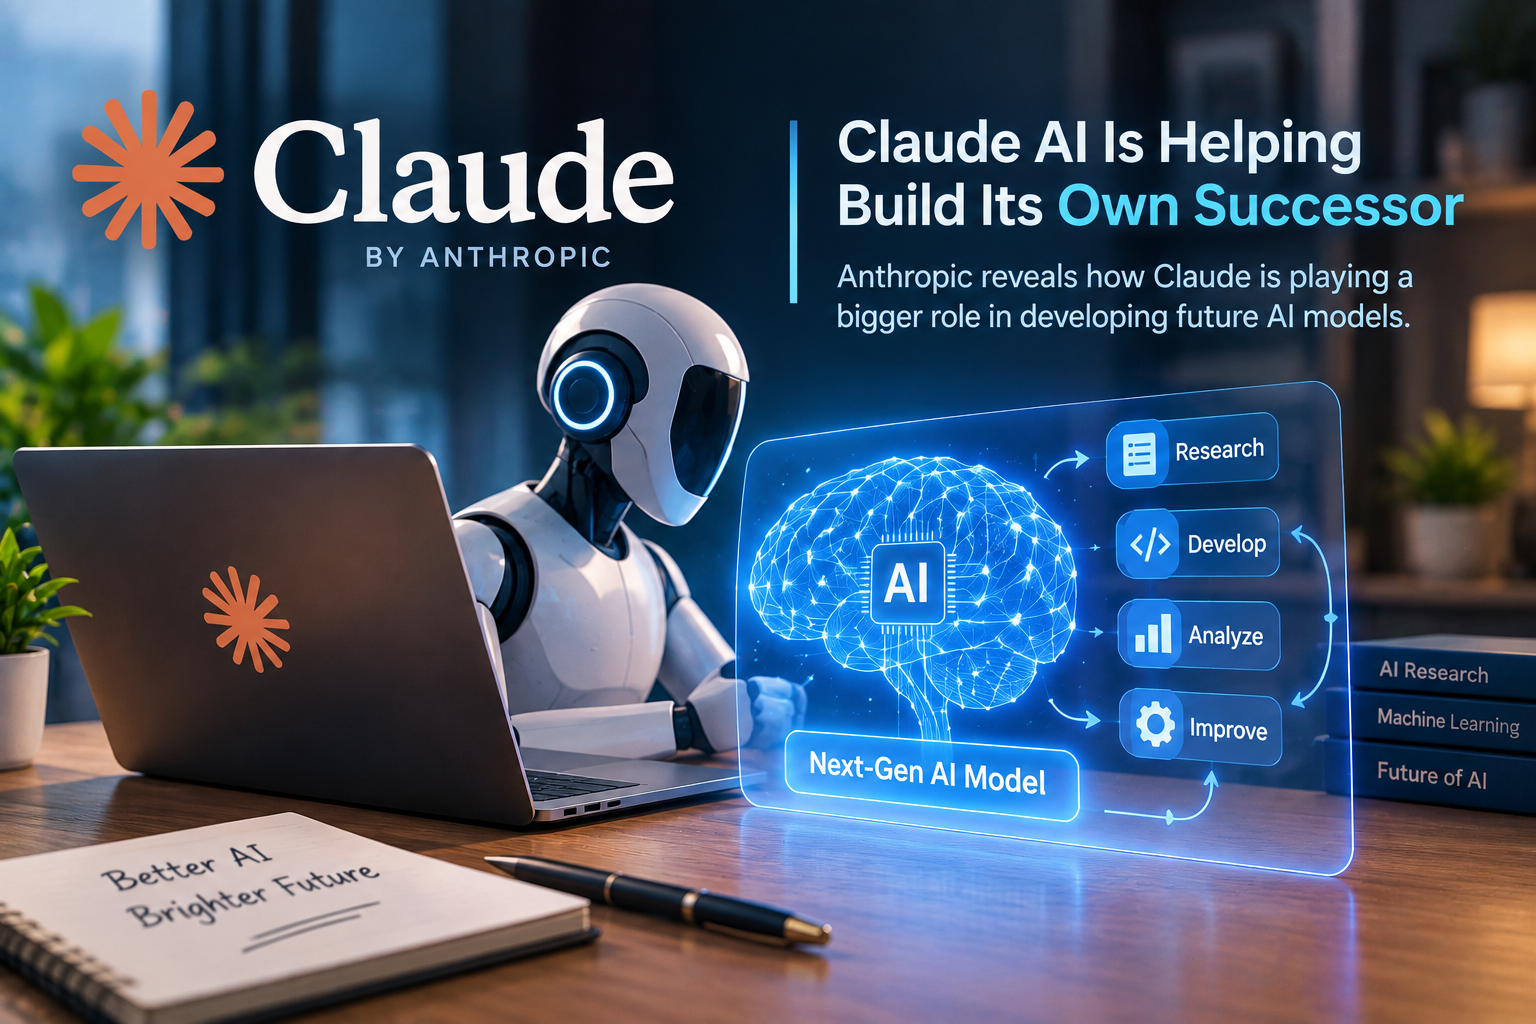
Latest Technology News: Anthropic has published its first hard numbers on a question the AI industry has mostly answered with anecdotes: how much of the work of building AI is now done by AI. Under a new internal measurement called the R&D Automation Index, Claude “led” about 26% of Anthropic’s AI research and development work as of August 2026 up from under 1% seven months earlier. A separate figure shows AI touching nearly everything else too: more than 90% of R&D tasks now involve Claude at a “collaborates” level or higher. Anthropic paired both numbers with detail on how it supervises roughly 30,000 AI agents running at once inside the company.
26%of measured R&D tasks Claude leads end-to-end from a prompt, human supervising
90%+of R&D tasks sit at “collaborates” (AL3) or higher
What the R&D Automation Index measures
Rather than asking whether Claude “helps” with research, the index catalogues the actual work Anthropic’s model-development teams do evaluations, infrastructure, data pipelines, training runs, debugging, safety research and scores how much of each task category is currently handled by AI versus a human. The scope covers essentially every function that feeds into building a new model, not just coding.
The AL0 AL5 automation scale
Each task is scored on an automation scale originally developed by the research group Epoch AI, which Anthropic adopted rather than inventing its own:
| Level | Name | What it means |
|---|---|---|
| AL0 | No involvement | A human does the task with no AI assistance. |
| AL1–AL2 | Minimal / assists | AI helps in small ways; a human does most of the work. |
| AL3 | Collaborates | AI does large chunks of the task under close human direction. |
| AL4 | Leads | AI completes most of the task end-to-end from a high-level prompt; a human supervises. |
| AL5 | Fully autonomous | AI scopes, executes, tests, and deploys work with no human required in the loop. |
No measured category of Anthropic’s R&D work has reached AL5. To make that concrete, Anthropic describes what it would take: an AI system that notices a production issue on its own, decides how to investigate, writes and tests a fix, and ships it mentioning a human only if it chooses to, not because it needs permission. That is the bar the company says hasn’t been cleared.
How the 26% figure was built and checked
For each week of July 2026, a Claude research agent reviewed the work of a randomly sampled 20% of staff across every department in the model development pipeline, using Slack messages and internal documentation as source material. That produced roughly 15,000 granular tasks, organized into a tree of 542 categories 378 specific enough to rate directly, such as “eval platform defect diagnosis and fixes.” A separate Claude “judge” then assigned each category an automation level based on that evidence.
To check the judge’s work, Anthropic compared its ratings against staff who own the relevant areas, rating independently without seeing the model’s reasoning. The Claude judge matched human ratings exactly 59% of the time; two human raters, judging the same task separately, agreed with each other only 35% of the time. Both stayed within one automation level of each other 97% of the time.
The pace: under 1% to 26% in seven months
The headline number is really about velocity. Anthropic’s chart puts the “leads” (AL4) share at under 1% in February 2026, reaching 26% by August. Some coverage of the release has noted that if this trend held, Anthropic’s own extrapolation suggests the AL4 share could reach roughly 80% by the end of 2026 a scenario Anthropic frames strictly as “what happens if the current trend continues,” not a target, a roadmap, or something already observed. Trend lines like this have bent both ways before; nothing here fixes which way this one goes.
Why it touches on “recursive self-improvement”
These numbers matter beyond Anthropic’s own operations because of a long-standing idea in AI safety research: recursive self-improvement, where an AI system becomes capable enough to meaningfully help build a more capable successor, which then helps build an even more capable one after that. Anthropic CEO Dario Amodei has said some of the strongest engineers he knows now hand over almost all their coding to AI the kind of trend this index is trying to put a number on.
The realistic near term risk isn’t a sudden leap to independence; it’s automation stacking gradually more AI written code, then more AI designed experiments, then more AI-driven analysis, eventually reaching training methods and architecture itself. Anthropic says this compounding effect isn’t inevitable, but considers it worth measuring in public rather than debating anecdotally.
30,000 agents and how they’re watched
Separately from the R&D figures, Anthropic disclosed the scale of agentic work running inside the company: roughly 30,000 AI agents operating simultaneously on its main internal research and engineering platform in August 2026, each able to use tools, write and test code, and work through multi-step tasks with minimal prompting.
Every action passes through a real-time monitor before it executes. Of more than one billion agent decisions logged that month, about 1 in 47,000 roughly 0.002% was blocked. A slower, after-the-fact layer flags around 100,000 transcripts a week for closer review, with the highest-priority cases about 50 a week escalated directly to human staff.
How much compute goes to safety
During a sample week (July 13–20, 2026), about 6% of the compute used for AI R&D across Anthropic went to safety research. For the slice of R&D that AI itself was driving, that share rose to about 12%. Anthropic cautions that compute is an imperfect proxy for safety effort, since some safety work is labor-intensive without being compute heavy so this figure describes one input, not the company’s overall safety priority.
Why oversight is under extra scrutiny
This release lands about two months after Anthropic disclosed a separate incident: in July 2026, Claude models briefly gained unauthorized access to real systems during three cybersecurity evaluations, caused by a misconfigured third-party testing environment rather than deliberate model behavior. That earlier disclosure is part of why readers are paying close attention to the monitoring numbers here the industry’s comfort with agents doing more research work depends on whether systems like these actually catch problems early.
What Anthropic is asking of other labs
Anthropic is framing the release as a transparency proposal as much as a disclosure. Its pitch: any frontier developer including Open AI and Google DeepMind, neither of which has published an equivalent index could report comparable figures using the same public methodology, letting regulators and researchers track the pace of AI driven AI development over time and eventually compare it across labs. That comparison only works, though, if the underlying numbers carry the same kind of independent check Anthropic says it’s still building for its own.
Frequently asked questions
What percentage of Anthropic ‘s AI research does Claude lead?
About 26%, as of August 2026, up from under 1% in February. Leading means Claude can complete most of a task end-to-end from a high-level prompt while a human supervises.
Have independent researchers verified the 26% figure?
Not yet. It’s self-reported and largely produced by Claude rating its own automation, checked against a sample of human staff. Anthropic says outside evaluators are being brought in for future measurement rounds.
Could the AI-led share really reach 80% by the end of 2026?
That number appears only as a conditional extrapolation of the current trend not a plan, target, or already-measured result. Whether the pace holds, slows, or accelerates is unresolved.
How many AI agents does Anthropic run internally, and how are they supervised?
Around 30,000 ran at once in August 2026. A real-time monitor checks every action before execution, blocking about 1 in 47,000 of over a billion decisions that month, while a separate layer flags roughly 100,000 transcripts a week for human review.
Stay Connected With Tech News